Enterprise AI Inference Costs: What Actually Drives the Cost of AI
TL;DR , Key Takeaways:
- AI inference cost is bigger than token price. Model size, input context, output tokens, retrieval, tool calls, concurrency, infrastructure and repeated requests all contribute.
- For API-priced LLMs, token consumption is a direct cost driver. For self-hosted systems, tokens translate into compute demand, memory use and throughput requirements rather than a simple per-token bill.
- Longer context is not free. Sending large amounts of retrieved or conversational context can increase both cost and latency.
- Tool-using and agentic systems can be significantly more expensive because one user request may trigger multiple model calls, retrieval steps and API calls.
- A smaller, purpose-trained model can be a better fit when the task is narrow, repetitive, high-volume or latency-sensitive.
- Knowledge graphs can reduce unnecessary context by helping the system identify the relevant business entities and relationships before retrieving information.
- Model size also affects memory, infrastructure, concurrency and deployment requirements.
- Shunya’s current Custom SLM benchmarks report 10× smaller models, 3× faster inference and 94% accuracy retention, along with substantially higher inference density and lower inference cost for its benchmarked workload. These are Shunya-reported results under its published methodology, not universal guarantees.
- The best enterprise AI architecture is usually about right-sizing intelligence, not using the largest model available for every task.
Enterprise AI costs are often reduced to one number:
price per million tokens.
That number matters, but it is only part of the picture.
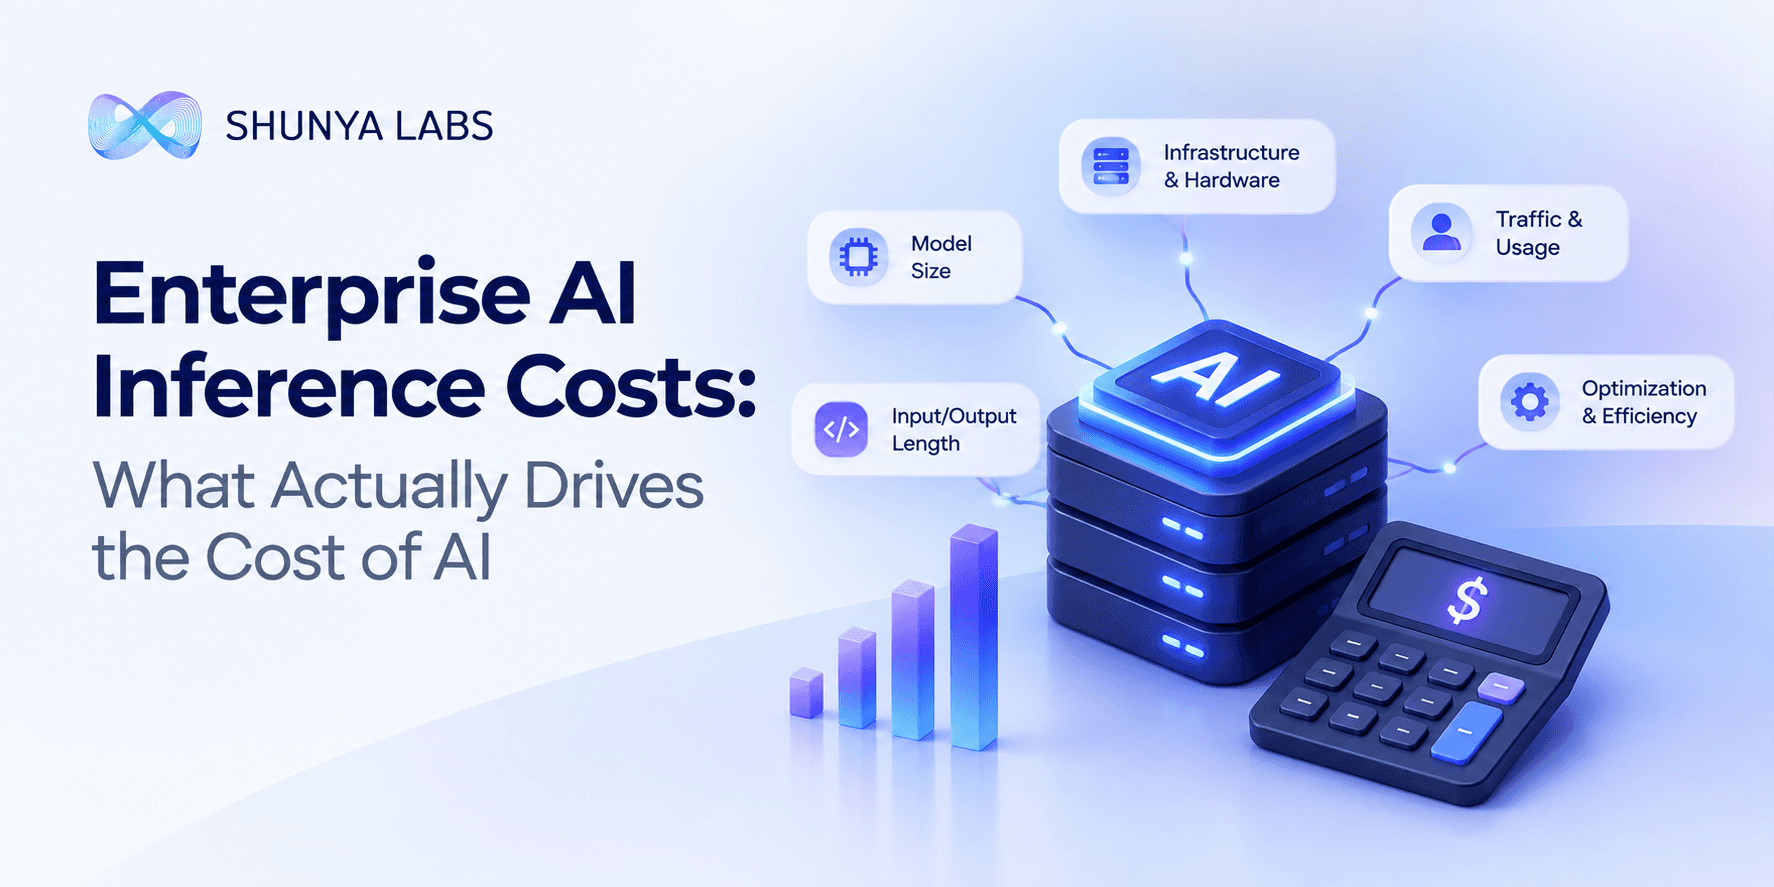
The real cost of running AI in production depends on how much the system processes, how much context it sends, how often it runs, how large the model is, how much infrastructure it needs, how much information it retrieves, and how many steps are required to complete a task.
For a simple enterprise workflow, sending every request to a large general-purpose LLM can mean paying for far more computation and context than the task actually needs.
That is why understanding AI inference costs matters before choosing a model or designing an enterprise AI architecture.
The right question is not simply:
“What does this model cost per token?”
It is:
“What will it cost us to complete this business task at the scale, latency and accuracy we need?”
What is AI inference cost?
Inference is the process of running a trained AI model to generate a result from an input.
For a text model, that might mean taking:
“Check whether this customer is eligible for a refund.”
and generating an answer.
For an enterprise AI system, inference can be much more than one model call.
A single user request might involve:
query understanding → retrieval → model inference → tool call → another model inference → response generation
For a voice agent, there can be additional stages:
speech recognition → reasoning → knowledge retrieval → tool execution → response generation → speech synthesis
Shunya’s enterprise voice agent architecture describes this as a five-stage workflow covering Listen, Ground, Decide, Translate and Speak, with speech, reasoning, knowledge and orchestration working together.
So the cost of AI should ultimately be measured at the system or task level, not just at the model level.
What actually drives enterprise AI costs?
There are several major cost drivers.
| Cost driver | Why it matters |
|---|---|
| Input tokens | More text sent to a model means more computation |
| Output tokens | Longer responses require more generation |
| Context length | Large prompts and retrieved knowledge increase processing and memory requirements |
| Model size | Larger models generally require more compute and memory |
| Number of requests | Higher usage increases total inference demand |
| Tool calls | Agents may trigger multiple external operations |
| Retrieval | Search, reranking and embeddings add processing |
| Concurrency | More simultaneous requests require more infrastructure |
| Latency requirements | Strict response-time targets may require additional capacity |
| Infrastructure | GPUs, CPUs, memory, storage and networking all affect TCO |
| Caching | Effective caching can reduce repeated computation |
| Deployment model | Cloud, VPC, on-prem and edge deployments have different economics |
The important thing is that these factors interact.
A small model handling millions of short requests may be more economically attractive than a large model handling a much smaller number of requests with very large contexts.
Token consumption is only part of the cost
Tokens are one of the easiest AI costs to understand because many model APIs are priced around them.
Suppose a model receives: 2,000 input tokens
and generates: 500 output tokens
That is one request containing 2,500 tokens.
Now imagine an enterprise application processing 1 million requests.
The total token volume becomes enormous.
But real enterprise applications can be more complicated than that.
A single request may include:
- system instructions
- conversation history
- retrieved documents
- customer information
- tool results
- previous model outputs
All of that can increase the amount of information the model processes.
This is especially important for agents and multi-turn applications.
A user may send one message, but the underlying system could make several model calls before completing the task.
That means the useful unit of measurement is often:
Cost per completed task
rather than:
Cost per individual model request
Context length can quietly increase AI costs
One of the easiest ways to increase AI consumption is to give the model too much context.
Consider a customer support assistant.
The user asks:
“What is the return policy for this product?”
A poorly designed system might retrieve:
- the full returns policy
- product documentation
- multiple FAQs
- older policy versions
- customer support manuals
- unrelated product information
The LLM then receives thousands of tokens even though the answer may only require a small section of one current policy.
That affects both cost and latency.
A better architecture identifies the relevant context first.
This is where knowledge graphs can become useful.
Instead of treating enterprise information as one large pool of documents, the system can identify:
Product → category → region → applicable policy
and then retrieve the smaller set of information relevant to that relationship.
Shunya’s current platform describes a knowledge graph that represents products, regulations, SOPs and workflows and grounds responses in enterprise-controlled information.
The goal is not: send more context to the model
The goal is: send the right context to the model
Bigger models do not automatically mean better economics
Large models are valuable for tasks that genuinely need broad knowledge or complex reasoning.
But many enterprise tasks are narrower.
For example:
- classify a customer intent
- detect a workflow step
- extract a structured field
- route a request
- validate a known rule
- identify a product
- normalise domain terminology
These tasks do not always need a large general-purpose model.
A custom Small Language Model can be trained around the enterprise’s specific workflows, terminology and decision processes.
Shunya’s current Custom SLM page reports 10× smaller models, 3× faster inference and 94% accuracy retention, alongside benchmarked results of 240+ concurrent users on a single L4 and approximately 20× lower inference cost for an equivalent workload. These figures are Shunya’s published benchmark results and should be interpreted within the methodology and workload used rather than as universal performance claims.
This is the core idea behind right-sized AI.
Use a model according to the complexity of the task, not according to the maximum capability available.
Model size changes infrastructure cost too
Token cost can be visible on an API bill.
Infrastructure cost is often less obvious.
A larger model can require more: GPU memory, RAM, compute, storage, network bandwidth, cooling, concurrency capacity
That affects how many requests one machine can handle and how much infrastructure must be provisioned during peak usage.
A purpose-trained model can change this equation.
Shunya’s current Custom SLM architecture is built around models ranging from 15M to 1.5B parameters, rather than assuming every enterprise workflow needs a very large general-purpose model.
This matters especially when a system needs to run at high concurrency.
The question becomes:
How many useful business tasks can this infrastructure complete per unit of compute?
That is much more useful than simply comparing parameter counts.
Cost per token is not the same as cost per business outcome
Imagine two systems.
System A
- A large general-purpose model handles every step.
- It receives a large context.
- It uses several tool calls.
- It generates long responses.
System B
- A purpose-trained model handles the common workflow.
- A knowledge graph identifies relevant business context.
- A deterministic rule handles the decision.
- A larger model is called only when genuinely complex reasoning is required.
Even if System A has a competitive token price, System B may still be less expensive at the workflow level because it uses fewer resources to complete the same task.
That leads to a more useful enterprise metric:
Cost per successful task
For example:
- cost per resolved customer request
- cost per completed KYC workflow
- cost per support ticket
- cost per completed voice conversation
- cost per processed claim
- cost per validated medical document
This is where model architecture starts to matter more than headline API pricing.
Agentic AI can increase the cost of a single request
Traditional chatbot architecture might have:
1 question → 1 model call
An AI agent may have:
1 question → plan → retrieve → tool call → observe → reason → tool call → final response
Every additional step can add processing.
The architecture therefore needs to control: how many model calls happen, which model handles each step, how much context is passed between steps, which tools are called, how often information is retrieved
This is another reason a large model does not need to sit at the centre of every part of the system.
A smaller specialised model can handle routing or classification.
A knowledge graph can narrow the search space.
A deterministic workflow can execute business rules.
A larger reasoning model can handle the genuinely ambiguous part.
Knowledge graphs can reduce unnecessary model work
A knowledge graph is not only an accuracy technology.
It can also become a cost optimisation mechanism.
Consider an enterprise with tens of thousands of products, policies, customer types and workflows.
A question might require only a tiny portion of that information.
Instead of sending a huge context to the LLM, the system can first establish:
- Which customer?
- Which product?
- Which region?
- Which policy?
- Which workflow?
Then retrieve the supporting evidence.
Shunya’s enterprise AI platform describes this model as keeping enterprise truth in a structured knowledge layer while the model generates the language around that context.
That separation can make an architecture both more grounded and more efficient.
Retrieval itself has a cost
RAG is often discussed as if retrieval is free.
It is not.
A production retrieval architecture can involve: document parsing, chunking, embedding, vector search, keyword search, reranking, metadata filtering, knowledge-graph traversal, context assembly
These operations consume compute and infrastructure too.
But that does not mean retrieval is a bad idea.
The question is whether retrieval reduces the more expensive work elsewhere.
If a lightweight retrieval step allows the system to send a much smaller context to a large model, the overall system can still be more efficient.
This is why enterprise AI economics should be evaluated across the entire architecture, not one individual component.
Repeated context is another hidden cost
Enterprise applications often repeat the same information.
A customer support system may repeatedly send:
- system instructions
- product information
- policy context
- conversation history
A voice agent may repeatedly work with the same business rules during a conversation.
Caching can help reduce unnecessary recomputation in these workflows.
The important distinction is that caching does not replace model inference.
Instead, it can allow parts of previously processed context or intermediate state to be reused, reducing redundant computation.
This becomes particularly useful for long-context and multi-turn workloads, where repeating the same context can become expensive.
Caching is therefore part of the broader enterprise inference architecture alongside: model size, context management, routing, retrieval, batching and concurrency.
This will become even more important as AI applications become more agentic and conversations become longer.
Memory and storage also affect the economics
There are two different questions enterprises should ask:
How much storage does the model require?
and
How much memory does inference require?
These are not the same.
Model weights may be stored on disk, but during inference the model needs access to the memory required to execute it.
Long contexts can also increase runtime memory requirements.
And higher concurrency means more simultaneous state needs to be handled.
This is why a smaller model can have benefits beyond token cost.
A model with a smaller footprint may be: easier to load, faster to deploy, cheaper to run, easier to host privately, easier to run at the edge and capable of higher inference density on the same hardware.
Shunya’s on-device AI models demonstrate the extreme end of this principle. Its Zero Tiny ONNX models are 5–15 MB, CPU-optimised, require no GPU, and can run without internet connectivity.
The point is not that every enterprise workload should run on a 5 MB model.
It is that model size should match the job.
AI does not always need the same infrastructure
Different workloads can require very different deployment architectures.
A high-volume customer support classifier might run comfortably on a small CPU-friendly model.
A real-time voice workflow might use a specialised speech model and an SLM.
A complex research assistant might need a larger reasoning model.
An edge device might require a tiny local model.
A regulated enterprise might require private VPC or on-premises deployment.
Shunya’s platform currently describes deployment across cloud, private VPC, on-premises and air-gapped environments, while its edge models are designed for CPU-only, offline inference.
This is why “Which model is cheapest?” is often the wrong question.
The better question is:
Which architecture gives us the required accuracy and reliability at the lowest total cost for this workload?
Accuracy still matters
Optimising purely for cost is another mistake. A cheaper model is not useful if it cannot complete the task accurately.
The goal should be: lower cost without sacrificing the accuracy the workflow actually needs.
This distinction matters because a specialised model can sometimes perform very well on a narrow task while being much smaller than a general-purpose model.
Shunya’s current Custom SLM benchmarks report 94% accuracy retention alongside lower latency and smaller models. Again, this is a Shunya-reported benchmark result, not a claim that every smaller model will outperform every larger one.
For speech AI, Shunya publishes separate benchmark results across speech recognition and other capabilities so that performance can be evaluated against defined datasets rather than only marketing demonstrations.
The same principle should apply to enterprise language models: measure the workload you actually care about.
What should enterprises measure instead of token price?
A stronger enterprise AI cost model looks at several metrics together.
1. Cost per successful task
How much does it cost to complete the business outcome?
2. Cost per user or conversation
Useful for customer-facing systems.
3. Tokens per successful task
Not just total token volume.
4. Average context size
How much information is the model processing for each request?
5. Model utilisation
How effectively is the available compute being used?
6. Inference density
How many concurrent workloads can the infrastructure support?
7. Latency
How quickly is the actual task completed?
8. Accuracy
Does the system produce the correct result?
9. Escalation rate
How often does a request need a larger model or human intervention?
This creates a more meaningful equation:
Enterprise AI efficiency = accuracy + latency + cost + throughput + reliability
not:
Enterprise AI efficiency = lowest token price
A practical way to reduce enterprise AI inference costs
Start with the business workflow.
Then ask:
Does this task require broad reasoning?
If not, consider a specialised model.
Does the task need a lot of enterprise context?
Use targeted retrieval and structured knowledge instead of passing everything into the model.
Does the same context repeat?
Look at caching and state reuse.
Does the workflow follow deterministic rules?
Keep those rules outside the model.
Does every step need the same model?
Use model routing.
Does every task need cloud inference?
Evaluate local or edge deployment.
Does every user need the same level of model complexity?
Use different models for different workloads.
This is the foundation of a right-sized AI architecture.
Why smaller models can change enterprise AI economics
The most interesting opportunity is not simply building a model that is smaller.
It is building a model that is smaller because it is purpose-built.
A generic model needs broad capabilities.
A purpose-trained model can focus on: your terminology, your workflows, your intents, your business rules, your structured outputs
That can reduce the amount of model capacity required for the task.
Shunya’s current Custom SLM approach is built around this principle. Its published benchmarks report 10× smaller models, 3× faster inference and lower infrastructure and inference costs for the evaluated workload.
Combined with a knowledge graph, the model does not have to carry the entire enterprise inside its parameters.
The architecture can divide responsibility:
- Knowledge graph → enterprise relationships
- Business rules → deterministic decisions
- Custom SLM → task-specific intelligence
- LLM → complex reasoning when required
- APIs → current system state
That is a fundamentally different way of thinking about enterprise AI.
The future of enterprise AI cost is about right-sizing intelligence
Enterprise AI does not have one universal cost model because it does not have one universal workload.
A customer support workflow, a clinical workflow, a financial workflow, a voice agent and an edge application can all have completely different requirements.
The same is true of models.
Some tasks need a large reasoning model.
Many do not.
The architecture should therefore allocate intelligence according to the task:
- small task → small model
- structured task → specialised model + knowledge
- complex reasoning → larger model
- deterministic workflow → rules and software
- edge task → lightweight local model
This is where the economics become interesting.
Instead of asking how to make one large model cheaper, enterprises can ask:
How much intelligence does this task actually need?
That question can lead to lower latency, lower infrastructure requirements, lower token usage and lower total inference cost without forcing every workload into the same model.
Final thoughts
Enterprise AI costs are not determined by one number.
They emerge from the architecture.
Tokens matter.
Context matters.
Model size matters.
Memory matters.
Concurrency matters.
Retrieval matters.
Tool calls matter.
Latency requirements matter.
Deployment matters.
And most importantly, the complexity of the task matters.
Using a large general-purpose model for every enterprise workflow can be like using a high-performance machine for every job, even when a purpose-built system would complete many of those jobs more efficiently.
The better approach is to right-size the intelligence.
Use the smallest model that can reliably solve the task.
Ground it in the right enterprise knowledge.
Keep deterministic logic outside the model.
Use larger reasoning models where they genuinely add value.
Reuse context where possible.
And measure the result by cost per successful business outcome, not just cost per token.
That is the difference between simply buying AI inference and actually engineering efficient enterprise AI.
Frequently Asked Questions
What determines the cost of AI inference?
AI inference cost depends on factors including input and output tokens, model size, context length, number of requests, retrieval, tool calls, concurrency, hardware, memory and deployment architecture.
Why are LLMs expensive to run?
Large LLMs can require significant compute and memory, and long prompts or repeated context can increase the amount of work performed for each request. High concurrency and multi-step agent workflows can increase infrastructure requirements further.
Does token usage determine LLM cost?
For usage-priced APIs, token consumption is often a direct cost driver. In self-hosted systems, tokens instead translate into compute demand, memory use, throughput and infrastructure utilisation.
How can enterprises reduce AI inference costs?
Common approaches include smaller purpose-trained models, model routing, better retrieval, shorter relevant context, caching, quantisation, batching and right-sized infrastructure.
Do smaller AI models cost less?
They can. Smaller models generally require less compute and memory, but the actual economics depend on the model, workload, hardware and deployment architecture. Shunya’s published Custom SLM benchmarks report substantially lower inference cost and higher inference density for its evaluated workload. (Shunya Labs)
Does RAG increase AI costs?
RAG introduces its own retrieval and infrastructure costs, but targeted retrieval can reduce the amount of context sent to a model. The overall result depends on the architecture and whether retrieval reduces more expensive downstream inference.
Can knowledge graphs reduce AI costs?
They can help reduce unnecessary context by identifying relevant entities and relationships before retrieval and generation. Their value is highest when enterprise questions depend on structured relationships.
Does every enterprise AI task need an LLM?
No. Many tasks such as classification, routing, extraction, terminology handling and workflow decisions can be handled using smaller specialised models or deterministic logic.
Can smaller models run without expensive GPUs?
Some can. Model size, architecture and optimisation determine hardware requirements. Shunya’s on-device models, for example, include 5–15 MB CPU-optimised models that do not require a GPU. (Shunya Labs)
What is the best way to measure enterprise AI cost?
Measure cost per successful business outcome, alongside token usage, latency, accuracy, concurrency and infrastructure utilisation.
Learn More
Explore Shunya’s Custom Small Language Models, enterprise AI platform, on-device AI models, enterprise voice agents, AI pricing, and published benchmarks.

Bio: Navvya works at the intersection of product strategy and applied AI research at Shunya Labs. With a background in human behaviour and communication, she writes about the people, markets, and technology behind voice AI, with a particular focus on how speech interfaces are reshaping access across emerging markets.