How to Reduce Token Usage in Voice AI Without Hurting Accuracy
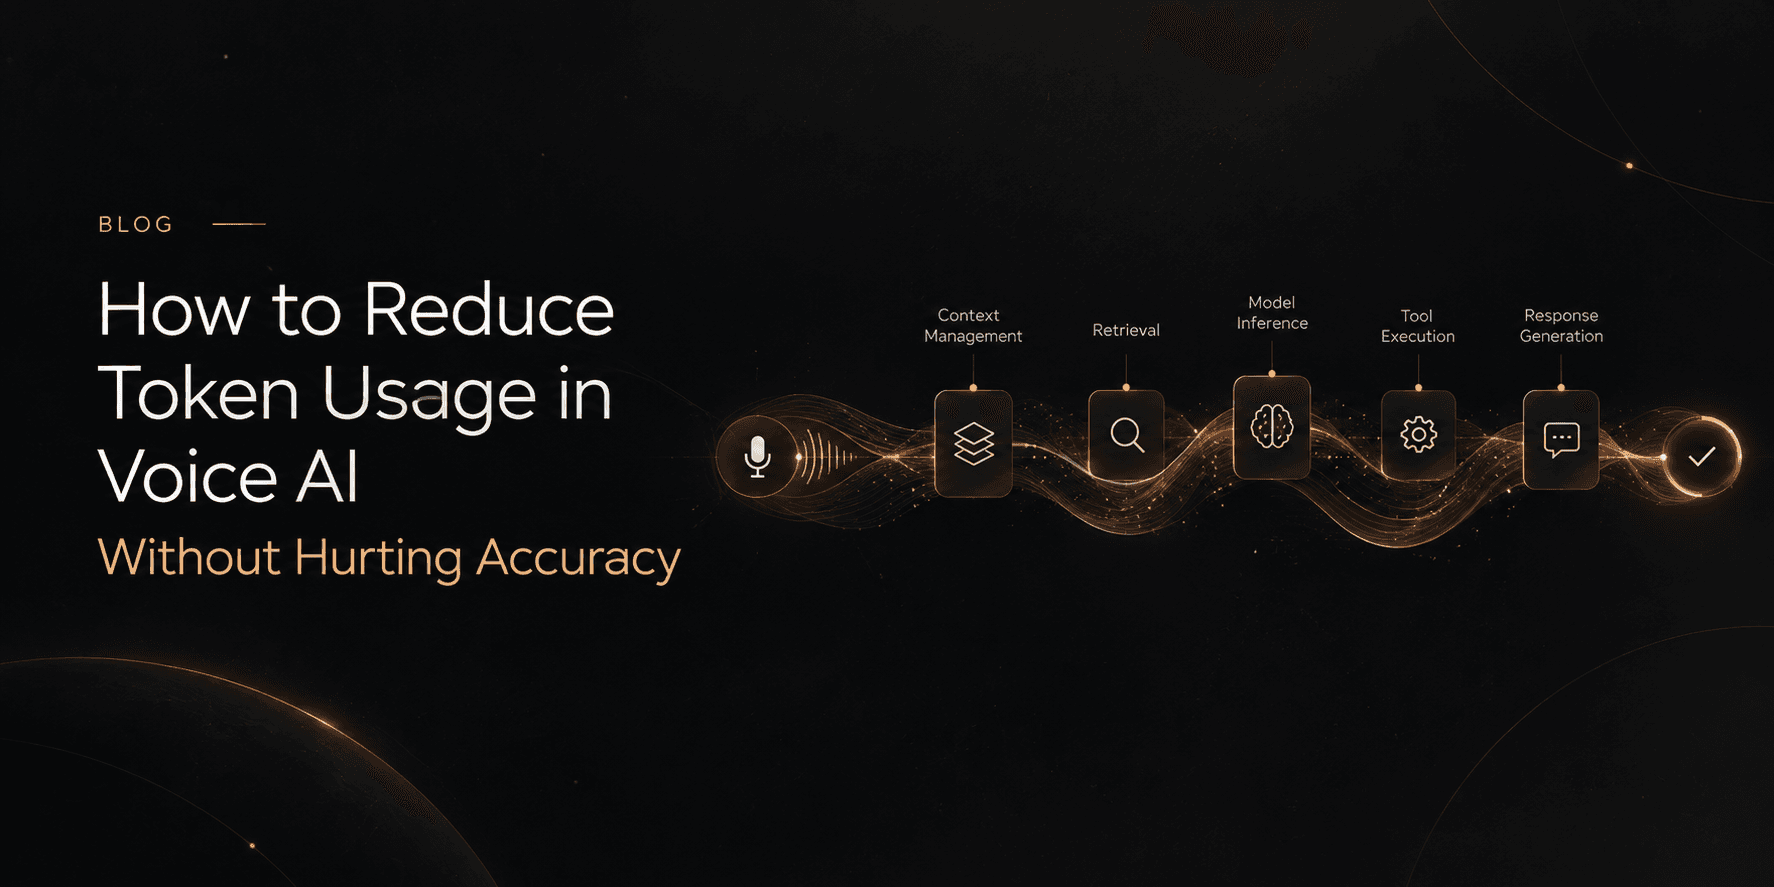
AI voice agents need to do more than process a customer’s latest sentence. They may need to remember earlier messages, retrieve business information, interpret customer intent, call external tools, and respond naturally in real time.
As these interactions become more complex, the amount of information sent to language models can grow quickly. A single customer request may involve conversation history, system instructions, retrieved documents, customer records, tool definitions, and responses from previous steps.
Processing all of this information on every turn can increase token consumption, inference costs, and response times. However, simply cutting context is not a reliable solution. Removing information the agent needs can lead to incorrect answers, failed tool calls, and incomplete customer interactions.
The goal is to reduce unnecessary processing while preserving the information required to complete a task correctly.
In this guide, we explore how to reduce token usage in voice AI through context engineering, structured memory, targeted retrieval, model selection, and caching, without compromising accuracy or customer experience.
Why Do AI Voice Agents Consume So Many Tokens?
A token is a unit of text processed by a language model. Depending on the model and tokenizer, tokens may represent whole words, parts of words, punctuation, or other text units. Token usage is therefore not the same as word count.
For an AI voice agent, token consumption can extend far beyond the customer’s spoken request.
Consider a customer asking:
“Can you check whether my order has shipped?”
The system may need to process:
- The customer’s current request.
- The conversation history and relevant preferences.
- Instructions defining how the agent should behave.
- Available tool definitions and their input requirements.
- Relevant order policies or business rules.
- Information retrieved from the order management system.
- Results returned by previous tool calls.
If the conversation continues, additional messages and tool results may be added to the context. In an agentic workflow, the same information may be passed through several model calls before the task is complete.
This creates an important distinction: the amount of information a system can process is not necessarily the amount it should process.
A larger context window can be valuable for complex tasks, but sending the entire conversation history and every potentially relevant document on every turn is often unnecessary.
Measure Token Usage Across the Entire Voice AI Pipeline
Before optimising token consumption, identify where the tokens are being used.
A voice agent typically combines speech processing, language understanding, knowledge retrieval, model inference, tool execution, and speech generation. Not every stage consumes language-model tokens in the same way.
For example, an audio-based model may process audio inputs differently from a text-based model. A conventional speech-to-text system may convert audio into text before passing it to a language model. A text-to-speech system may then generate audio from the final response.
The cost profile depends on the architecture, the models being used, and the provider’s pricing.
Track the main sources of consumption
Input tokens: These include instructions, conversation history, retrieved information, tool definitions, and the latest user message.
Output tokens: These are generated by the model. Long responses, unnecessary explanations, and verbose intermediate outputs can increase consumption.
Repeated context: The same instructions, policies, or conversation details may be sent across multiple model calls.
Tool-related context: Tool descriptions, arguments, results, and error messages can accumulate during multi-step workflows.
Repeated model calls: An agent may call the model multiple times to interpret a request, decide on an action, process a tool response, and formulate a final answer.
A useful starting point is to measure input and output tokens per turn, the number of model calls per task, and the total token consumption per completed interaction.
For voice applications, it is also important to distinguish between a conversational turn and a completed task. A customer might need several turns to complete one order change or resolve one support issue.
Establish a baseline before making changes
Record the following metrics for representative customer journeys:
- Average input and output tokens per turn.
- Total tokens per completed task.
- Number of model calls and tool calls per task.
- Task completion rate.
- Accuracy of responses and tool arguments.
- Average response latency.
- Cost per successful task.
Segment these measurements by workflow, language, model, and conversation complexity where possible.
This baseline helps identify whether the largest opportunity lies in reducing repeated context, shortening generated responses, improving retrieval, or eliminating unnecessary model calls.
Send Relevant Context Instead of the Entire Conversation History
Conversation history helps a voice agent understand references, corrections, and previous decisions. However, retaining every message indefinitely can make each subsequent model request larger than necessary.
Imagine a customer who has already provided an order number, selected a replacement product, and confirmed a delivery address. If the agent repeatedly sends the entire conversation, including unrelated small talk and previous explanations, the model may process far more text than the next step requires.
The solution is not to discard history indiscriminately. It is to distinguish information that remains necessary from information that no longer contributes to the current task.
Use task-aware context management
A practical approach is to maintain a compact representation of the active task.
For an order replacement, this might include:
- Customer intent: replace an item.
- Order identifier: verified order ID.
- Selected replacement: product and size.
- Required checks: inventory and replacement eligibility.
- Current workflow state: awaiting inventory confirmation.
- Outstanding question: whether the requested item is available.
The model does not necessarily need every previous message to continue the workflow. It needs the information required to make the next correct decision.
This can be implemented through structured state, carefully designed summaries, or a combination of both.
Preserve exact information when it matters
Summarisation should not introduce ambiguity into critical fields. Identifiers, payment amounts, dates, addresses, consent status, and transaction outcomes should be preserved in validated structured fields or retrieved from the authoritative system when needed.
A summary should also distinguish between confirmed facts and assumptions. For example, “customer requested a cancellation” must not become “order cancelled” unless the cancellation has actually been confirmed by the relevant system.
Use summaries to reduce repetitive conversational text, not as a substitute for authoritative records.
Use Structured Memory Instead of Repeating Long Conversations
A voice agent often needs to remember facts across multiple turns. The challenge is deciding what to retain, how to represent it, and when to retrieve it.
Keeping the full transcript is one option, but it is not always the most efficient or reliable approach.
Structured memory stores relevant information in a more compact form. Depending on the application, this may include the current task, verified customer details, previous decisions, preferences, or unresolved actions.
For example, a support agent might maintain the following state:
| Field | Stored value |
|---|---|
| Intent | Check payment status |
| Account reference | Verified account identifier |
| Payment date | Customer-provided date |
| Verification status | Completed |
| Current status | Awaiting ledger response |
| Next action | Query payment system |
The agent can use this state to determine the next step without reconstructing the entire conversation every time.
What should be stored in memory?
The right memory structure depends on the task, but useful principles include:
Store task-relevant information. Retain details that influence future decisions or prevent the customer from repeating information.
Separate structured facts from narrative context. A verified account identifier should not be buried in a paragraph that the model must interpret again.
Track state changes explicitly. Record whether an action has been requested, attempted, confirmed, or failed.
Set clear retention boundaries. Information should remain available only as long as it is needed and permitted under the application’s privacy and data-retention requirements.
Retrieve authoritative facts when necessary. Memory may preserve the fact that a payment was checked earlier, but a workflow requiring the latest balance should query the appropriate system again.
Structured memory can reduce repeated context while improving consistency. However, it must be designed carefully. An incomplete or outdated summary can be more damaging than a longer transcript that contains the original information.
Retrieve Only the Knowledge Needed for the Current Request
Enterprise voice agents often need access to large collections of information, including policies, product documentation, standard operating procedures, customer records, and internal knowledge bases.
Sending entire documents or large collections of search results to a model can increase token consumption without necessarily improving the answer.
Retrieval-based approaches help by selecting relevant information before the model generates a response.
Use targeted retrieval
Consider a customer asking whether an order can be returned after 30 days.
The agent may need to retrieve the applicable return policy, the order date, the product category, and any relevant exceptions. It probably does not need the entire product catalogue, unrelated support articles, or every policy document in the company.
A targeted retrieval workflow can:
- Identify the intent and relevant entities.
- Determine which information sources are required.
- Retrieve the relevant policy or record.
- Apply the applicable business rules.
- Pass the necessary evidence to the model.
- Generate a response grounded in that information.
The key is to reduce irrelevant context without removing information needed to answer correctly.
Where knowledge graphs can help
Document retrieval is useful when the answer is contained in a passage or policy. Some enterprise questions, however, depend on relationships between multiple entities.
For example, determining whether a customer qualifies for a particular offer may require connecting the customer segment, product, region, eligibility conditions, and current account status.
A knowledge graph can represent these entities and relationships explicitly, helping the system identify which information is relevant to the query. The resulting context can then be limited to the facts and relationships needed for the decision.
Knowledge graphs do not automatically guarantee accurate answers, and they do not replace every database or document retrieval system. Their value depends on the quality of the underlying data, the relationships represented, and how the application uses them.
The broader principle is to retrieve information according to the structure of the task rather than supplying large volumes of context by default.
For more on the relationship between enterprise knowledge and reliable AI, explore the Shunya Labs enterprise voice AI platform, which brings speech AI, knowledge graphs, and purpose-trained Small Language Models into a unified platform.
Reduce Repeated Instructions and Unnecessary Tool Context
Tool-using agents often include descriptions of available tools, their parameters, usage instructions, and previous tool results in model requests.
These definitions are important because they help the model choose the correct action. But tool context can become expensive when applications expose many tools that are irrelevant to the current task or repeatedly include large amounts of redundant information.
Make tool definitions concise and specific
Each tool should have a clear purpose, defined inputs, and an unambiguous description of when it should be used.
Avoid long, repetitive descriptions that restate general instructions already provided elsewhere. At the same time, do not remove essential constraints, parameter descriptions, or information required for correct tool selection.
Where the architecture supports it, make only relevant tools available to the current workflow. For example, an agent checking order status may not need access to every payment, refund, inventory, and account-management tool.
This reduces unnecessary context and can also reduce the number of incorrect tool selections.
Keep tool results focused
An API may return dozens of fields when the agent needs only a few.
If the model needs the order status, expected delivery date, and tracking reference, passing an entire customer record or a large raw API response may be unnecessary.
A better approach is to extract the required fields, validate them, and pass a concise result to the model.
However, tool outputs should not be shortened so aggressively that important warnings, error states, or conditions are lost. A response indicating that an order is “pending verification” must not be simplified to “pending” if the distinction changes the next action.
Avoid unnecessary model calls
Not every workflow step requires a fresh language-model decision.
Deterministic operations, such as validating a required field, checking a fixed rule, or formatting a known data structure, may be handled by application logic.
For example, a voice agent does not need to ask a language model to determine whether a required account identifier is missing if a simple validation rule can detect it.
Reducing unnecessary model calls can lower token consumption and improve latency. The important distinction is between predictable operations that can be handled deterministically and decisions that genuinely require language understanding.
Use Smaller, Purpose-Trained Models for Suitable Tasks
Using a large language model for every stage of a voice interaction can be inefficient, particularly when some tasks are narrow, repetitive, and well-defined.
Examples include classifying common customer intents, extracting specific fields, routing requests, or identifying whether a conversation should be escalated.
A smaller, purpose-trained Small Language Model (SLM) may be suitable for these tasks if it meets the required quality, reliability, and latency standards.
Match the model to the task
A practical architecture may use different components for different responsibilities:
- A speech recognition model converts audio into text.
- A smaller model classifies the request or extracts structured details.
- A retrieval system finds relevant enterprise information.
- Business logic validates eligibility and mandatory conditions.
- A language model generates a grounded explanation when flexible language generation is needed.
- An application or API executes the requested action.
This does not mean that every voice agent should use multiple models. Additional components introduce integration complexity and can create their own latency and failure points.
The right architecture depends on the complexity of the workflow, the available models, the quality requirements, and the cost of errors.
Evaluate quality before switching models
A smaller model should not be selected based on parameter count or inference speed alone.
Test it against representative tasks, including ambiguous requests, unusual phrasing, multilingual inputs, domain terminology, and cases where the correct response is to ask a question or escalate.
Compare its accuracy and task completion rate with the existing approach. A cheaper model that creates more retries, failed actions, or human handoffs may increase the overall cost of completing a task.
The objective is to use the least resource-intensive approach that reliably meets the requirements of each step.
Use Prompt Caching for Repeated Context
Some context changes with every user request. Other context remains stable across many requests.
For example, an enterprise voice agent may use the same core instructions, tool definitions, and workflow guidance for thousands of interactions. Reprocessing identical input context can create avoidable overhead, depending on the model and serving architecture.
Prompt caching allows supported systems to reuse processing associated with repeated prompt prefixes. It can reduce the cost of repeated input tokens and, in supported configurations, improve response latency.
How to make caching more effective
Keep stable context consistent. Reusable instructions and tool definitions should not change unnecessarily between requests.
Separate stable information from dynamic data. Put shared instructions and reusable reference material in a consistent position, while keeping customer-specific details and the current request in the appropriate dynamic portion of the input.
Measure cache reuse. Monitor cached input tokens, cache hit rates where available, latency, and actual token costs. Caching benefits depend on the provider, model, pricing structure, and request pattern.
Respect data-handling requirements. Caching strategies must align with the application’s security, privacy, retention, and regional-processing requirements.
Caching is not the same as reducing the number of tokens in a request. It changes how repeated context may be processed and billed. It also does not eliminate the need to send relevant context or guarantee that every request will receive a cache hit.
For many applications, caching works best alongside context management, retrieval, and structured memory rather than as a standalone optimisation.
Compress Context Without Removing Critical Information
Context compression aims to represent useful information with fewer tokens. This can involve summarising conversation history, removing duplication, restructuring information, or retaining only the details needed for the current task.
The challenge is that compression can remove information that appears unimportant but changes the correct answer.
For example, summarising “the customer asked to cancel, but the cancellation was rejected because the order had already shipped” as “customer requested cancellation” loses the outcome of the request. A subsequent model call might attempt the cancellation again or misinform the customer.
Apply task-aware compression
A useful compression strategy should preserve:
- The customer’s current intent.
- Verified facts and required identifiers.
- Relevant decisions and their outcomes.
- Business constraints and unresolved conditions.
- The current workflow state.
- The next action or outstanding question.
Remove duplicated explanations, irrelevant conversational details, and tool output that is no longer needed.
For high-risk actions, retain explicit evidence of verification and execution. For low-risk conversational tasks, a shorter summary may be sufficient.
Compression quality should be tested against the original context. Compare whether the system makes the same correct decisions, follows the same business rules, and reaches the same task outcomes when using the compressed representation.
Measure Token Efficiency Without Sacrificing Accuracy
Token reduction should never be evaluated in isolation. An optimisation that reduces input consumption but increases errors, retries, or escalations may be a poor trade-off.
For enterprise voice AI, the more useful question is whether the system completes the same work with fewer resources and without reducing reliability.
Metrics to track
| Metric | What it tells you |
|---|---|
| Input tokens per turn | How much context is processed for each model request |
| Output tokens per turn | How much text the model generates |
| Total tokens per task | The token consumption required to complete a customer request |
| Model calls per task | Whether the workflow makes unnecessary inference calls |
| Task completion rate | Whether the customer’s intended outcome is achieved |
| Groundedness and answer accuracy | Whether responses are supported by the available evidence |
| Tool execution accuracy | Whether the correct actions are selected and executed |
| Retry and escalation rates | Whether optimisation is creating additional failures or handoffs |
| Latency per completed task | Whether the overall interaction becomes faster |
| Cost per successful task | Whether the resource savings translate into better economics |
Run controlled comparisons
Start with a representative evaluation set and record the baseline performance.
Then change one part of the system at a time. For example, compare full conversation history with structured memory, broad retrieval with targeted retrieval, or a large model with a suitable purpose-trained model.
For each version, compare token usage alongside accuracy, task completion, latency, retries, and escalation rates.
Include difficult cases such as interrupted conversations, corrections, missing information, multilingual speech, failed APIs, and requests that require human approval.
This helps identify optimisations that reduce unnecessary processing while preserving the system’s ability to complete the task correctly.
A Practical Checklist for Reducing Token Usage in Voice AI
Before deploying an optimisation, use the following checklist:
- Measure input and output token consumption across the complete workflow.
- Identify repeated instructions, unnecessary history, and oversized tool results.
- Replace full transcripts with task-aware summaries or structured state where appropriate.
- Preserve critical identifiers, verified facts, and workflow outcomes.
- Retrieve only the knowledge required for the current decision.
- Use concise, well-defined tool schemas and focused tool outputs.
- Handle deterministic checks through application logic where appropriate.
- Evaluate smaller, purpose-trained models for bounded tasks.
- Use prompt caching where supported and beneficial.
- Test compression and retrieval changes against a representative evaluation set.
- Monitor task completion, grounding, tool accuracy, latency, and cost after deployment.
Conclusion: Reduce Unnecessary Context, Not Necessary Intelligence
Reducing token usage in voice AI is not simply a matter of shortening prompts or selecting a smaller model. It requires understanding how information moves through the entire system and deciding what each stage actually needs.
Structured memory can reduce repeated conversation history. Targeted retrieval can limit irrelevant business information. Concise tool definitions and focused API responses can prevent context from growing unnecessarily. Smaller, purpose-trained models can handle suitable tasks efficiently, while prompt caching can reduce repeated processing where supported.
Each optimisation should be evaluated against the same requirement: the agent must continue to understand the request, use reliable information, follow business rules, and complete the task correctly.
The objective is not the smallest possible prompt. It is the smallest useful context that preserves the information needed for a reliable outcome.
For enterprises building production voice AI, this makes token efficiency an architectural consideration rather than just a prompt-level adjustment.
Explore Shunya Labs to learn how speech AI, knowledge graphs, purpose-trained models, and enterprise deployment capabilities can work together to build more efficient voice AI systems.

Bio: Navvya works at the intersection of product strategy and applied AI research at Shunya Labs. With a background in human behaviour and communication, she writes about the people, markets, and technology behind voice AI, with a particular focus on how speech interfaces are reshaping access across emerging markets.