LLM Inference Cost Explained: Why Token Consumption Matters at Enterprise Scale
TL;DR , Key Takeaways:
- AI costs increase when applications process more information and make more model calls.
- Tokens are one way of measuring how much information an LLM processes and generates.
- Long prompts, large document collections, conversation history and repeated context can increase token usage even when the user’s question is very short.
- AI agents can use significantly more tokens because one user request may involve multiple AI steps.
- Better retrieval means less unnecessary information goes into the model.
- Knowledge graphs can help identify the relevant business context before the model processes it.
- Smaller, purpose-trained models can handle many narrow enterprise tasks without requiring the same level of model capacity as a large general-purpose LLM.
- Shorter, more focused responses can also reduce unnecessary generation.
- Caching and model routing can help avoid repeating the same work.
- The most useful business metric is cost per successful task, not just cost per million tokens.
- The best way to reduce AI costs is often to make the architecture do less unnecessary work.
When businesses start using generative AI in production, one of the first questions is usually:
How much does an LLM actually cost?
The answer is more complicated than a simple price per million tokens.
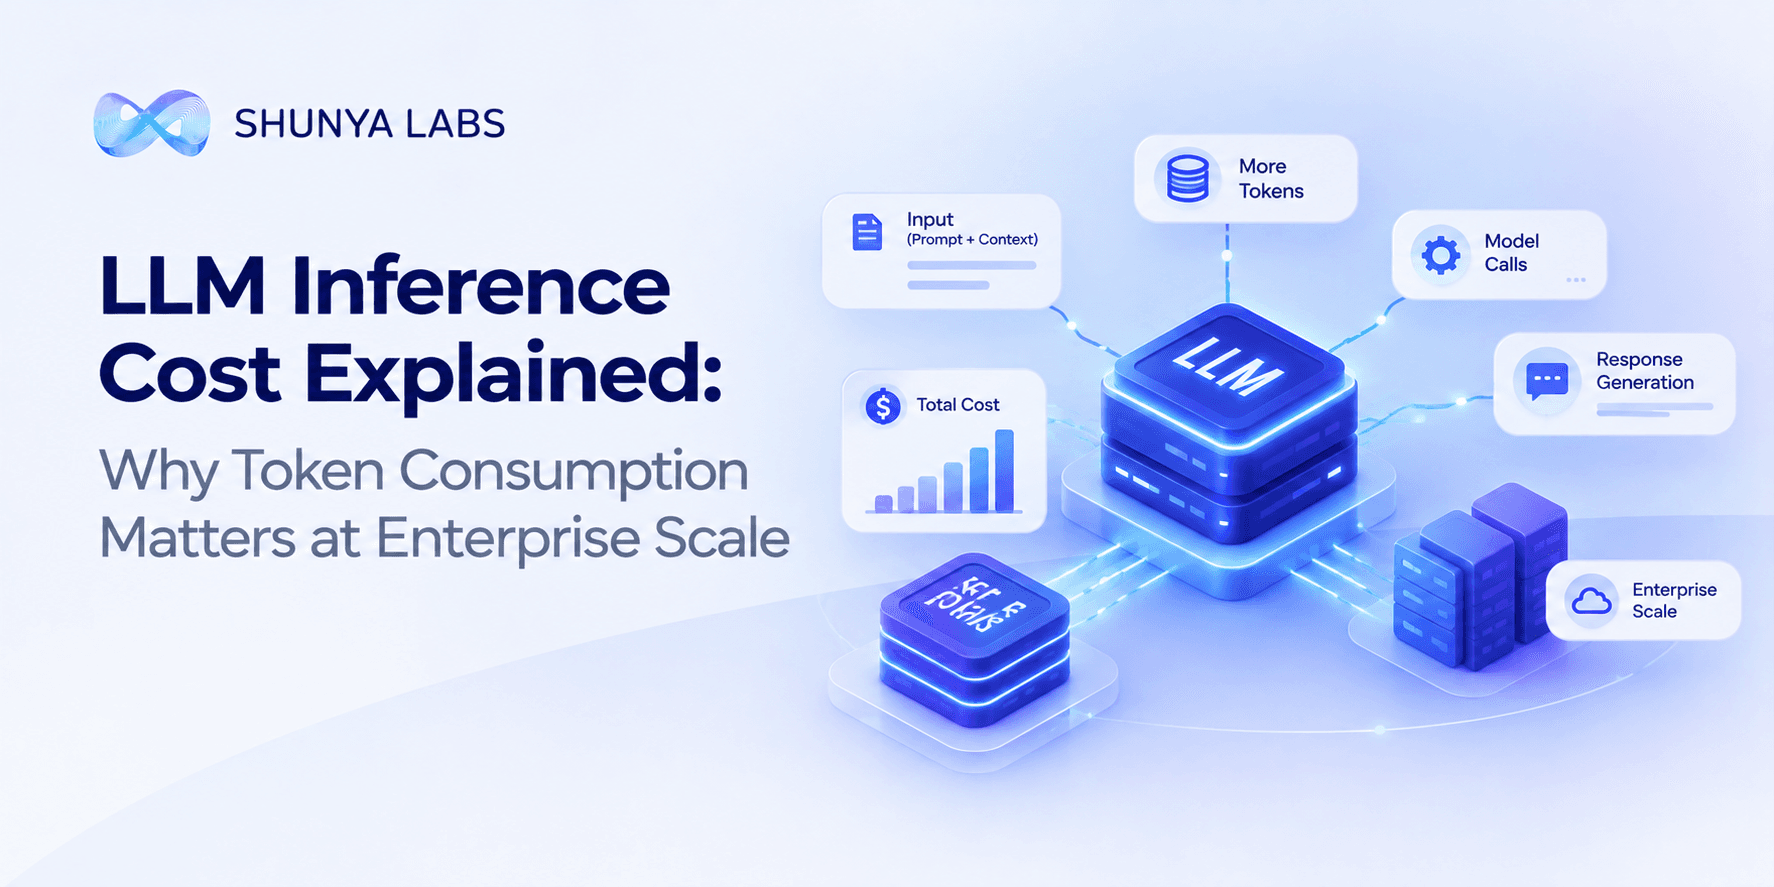
The amount an enterprise spends on AI depends on how much information the model receives, how often it is used, how much it generates, how many times it is called during a task, and how much context the application sends along with each request.
This becomes especially important at enterprise scale. A few extra hundred tokens may not seem significant in one interaction. Across hundreds of thousands or millions of requests, they can become a meaningful part of the total AI workload.
That is why token consumption matters.
But there is an even more useful way to think about it:
The goal is not simply to reduce tokens. The goal is to avoid making the AI process information it does not actually need.
For enterprises, that means looking at the entire AI architecture, from the model and its context to retrieval, knowledge, workflows and the number of times AI is called to complete one task.
What are tokens in AI?
When an LLM processes text, it breaks that text into smaller pieces called tokens.
You do not need to think of tokens as a technical concept to understand their business impact.
A useful way to think about them is:
Tokens are roughly the amount of text the AI has to read and write.
That text can come from many places.
For example, an enterprise AI assistant might process:
- The user’s question
- System instructions
- Previous conversation
- Company policies
- Retrieved documents
- Customer information
- Tool or API results
- The final response
So even when a user asks a five-word question, the AI may actually be processing much more information behind the scenes.
That is where token consumption can increase.
Why does token consumption matter?
If an AI system is used once, token efficiency may not seem especially important.
Enterprise AI is different.
A customer support assistant might handle thousands of conversations every day. An employee assistant might answer tens of thousands of questions every month. A voice agent may process millions of minutes of customer interactions over time.
At that scale, small differences in the amount of information processed per task can add up quickly.
For example, imagine two systems:
System A processes around 1,000 tokens per task.
System B processes around 3,000 tokens per task.
The difference may feel small for one request.
Across one million requests, System B has processed 2 billion more tokens.
The exact cost depends on the model and infrastructure, but the principle is simple:
Small amounts of unnecessary work become meaningful when an AI system operates at scale.
Why is my AI usage so expensive?
Businesses often look at the model’s published token price and assume that is the main reason an AI application costs more than expected.
In practice, several things can increase the total workload.
1. The AI receives too much information
A user may ask:
“Can I return this product?”
But the application may send the AI:
the full return policy, product documentation, previous customer conversations, FAQs, internal instructions and multiple related documents.
The answer may only need a small part of that information.
The model still has to process what it receives.
2. Conversations get longer
A chatbot or AI assistant may include previous messages every time a user asks a new question.
The conversation might begin with:
“I want to change my plan.”
A few messages later, the system may be carrying a large amount of previous context.
The user’s latest question may be short, but the total information being processed is not.
3. AI agents can make several model calls
An agent may need to:
understand a request → search for information → interpret the result → call a business system → check the result → generate a response
The user sees one answer.
The system may have performed several AI operations to produce it.
4. Responses may be longer than necessary
Not every business task needs a detailed written response.
A workflow may only need:
approved = true
next step = schedule callback
Generating a long explanation when the next system only needs a structured result creates unnecessary work.
Why longer context can make AI more expensive
One of the most common causes of unnecessary AI consumption is too much context.
Context simply means the information the model receives alongside the user’s request.
Consider an enterprise assistant answering:
“What is the refund policy for this customer?”
A well-designed system might identify:
- the customer’s product
- the region
- the applicable policy
- and retrieve the relevant information.
A less efficient system might provide:
- every refund document
- every product policy
- old versions
- support manuals
- FAQs
- the entire conversation
The second system is giving the model much more information than it needs.
This is why more context does not automatically mean better AI.
The better goal is:
Give the AI enough information to answer correctly, but not so much that it has to process irrelevant information.
How RAG can reduce unnecessary token usage
RAG is often introduced as a way to make AI responses more accurate by giving the model access to enterprise information.
It can also help with efficiency.
Instead of sending the entire company knowledge base to the AI, the system can search for information relevant to the user’s question and provide only the useful parts.
For example:
User asks about a product
→ identify the product
→ find the relevant policy
→ retrieve the relevant section
→ generate the answer
This is much more efficient than sending dozens of documents and asking the model to figure out which one matters.
Our enterprise AI platform is designed around this kind of knowledge-grounded architecture, combining enterprise knowledge, retrieval, structured context and purpose-trained models.
How knowledge graphs can help reduce unnecessary context
RAG is useful when the answer can be found in relevant documents.
But many enterprise questions depend on relationships.
For example:
“Which customers using Product A in India are affected by this policy?”
The system may need to understand:
Customer → uses → Product A
Product A → sold in → India
Product A → governed by → Policy B
A knowledge graph can represent those relationships before the model starts generating a response.
That can help the system narrow down:
- which customer
- which product
- which region
- which policy
- which documents
Only then does the model need to process the supporting information.
This makes knowledge graphs useful for more than accuracy. They can also help reduce unnecessary context and computation.
Why AI agents can consume more tokens than expected
AI agents are different from a simple question-and-answer application.
A traditional AI interaction may look like:
User → AI → Answer
An agent might look more like:
User → understand request → search → check information → call tool → review result → answer
Every additional AI step can create more processing.
This means enterprises should not only ask:
How much does one model call cost?
They should also ask:
How many AI calls does it take to complete one business task?
This is particularly important for applications that perform actions in systems such as CRM, ERP, ticketing, payment or scheduling platforms.
Do all AI tasks need a large LLM?
No.
This is one of the biggest opportunities for reducing enterprise AI costs.
Many business tasks are relatively narrow and repeatable.
Examples include:
- Intent classification
- Request routing
- Entity extraction
- Document classification
- Policy matching
- Structured data extraction
- Workflow-state detection
- Domain-specific terminology
- Simple customer-support tasks
These workloads often do not require the broad capabilities of a large general-purpose LLM.
A purpose-trained Custom SLM can be designed around the specific terminology and workflows that matter to the business.
Our published Custom SLM benchmarks report 10× smaller models and 3× faster inference, along with lower inference cost for the evaluated workload.
The point is not that smaller models should replace large models everywhere.
The point is:
Do not spend large-model compute on tasks that do not need large-model intelligence.
Smaller models can reduce more than token costs
An SLM does not necessarily reduce the number of tokens in a request.
What it can reduce is the amount of compute required to process those tokens.
That can affect: inference cost, latency, memory, GPU requirements, concurrency, infrastructure utilisation.
This becomes particularly important at high volume.
A specialised model handling a routine enterprise task millions of times can be a very different economic proposition from using a large general-purpose model for every request.
Our Custom SLM architecture is built around this idea of right-sized intelligence.
Why response length matters too
Businesses often think about how much information they send into an LLM.
The amount the model generates matters too.
Suppose an application needs to answer:
“Is this account eligible?”
The business may only need:
Eligible: Yes
But if the model generates several paragraphs explaining the decision, the system is producing more output than the workflow requires.
This matters especially for high-volume applications.
The right response length depends on the use case.
A customer may need a detailed explanation.
A downstream API may need a structured response.
An internal workflow may need only a classification.
The architecture should match the output to the job.
Can caching reduce AI costs?
Yes, when the same information is repeatedly processed.
Enterprise AI applications often reuse things such as:
- system instructions
- product information
- policies
- conversation context
- workflow information
Instead of repeatedly doing the same work, appropriate caching mechanisms can allow parts of the processing to be reused.
The key idea is simple:
Do not repeatedly calculate something that has not changed.
This becomes particularly useful for long conversations, repetitive workflows and AI agents that revisit the same context.
Caching does not eliminate inference, but it can reduce unnecessary repeated work.
Model routing can reduce unnecessary LLM usage
Another way to control AI consumption is to decide which model should handle each request.
Instead of:
Every request → large LLM
a business can use:
Simple request → Custom SLM
Structured enterprise request → SLM + knowledge
Complex reasoning → larger LLM
Deterministic rule → software or business logic
This is the idea behind model routing for enterprise AI.
It allows expensive model capacity to be reserved for requests that genuinely need it.
That can improve both cost and latency without forcing the entire application onto a smaller model.
The real cost is cost per successful task
Token price is useful for comparing AI services.
But enterprises need a bigger picture.
Suppose one system appears cheaper because its token price is lower.
But it:
- uses more context
- needs more retries
- makes more model calls
- produces more errors
- requires more human escalation
Another system may have a higher price per token but complete each task with:
- less context
- fewer calls
- fewer failures
- less infrastructure
The second system may have a lower cost per successful business outcome.
That is the metric enterprises should ultimately care about.
Examples include:
- Cost per resolved support request
- Cost per completed customer interaction
- Cost per processed document
- Cost per completed KYC workflow
- Cost per successful transaction
- Cost per completed voice conversation
The question is not:
“How cheap is each token?”
It is:
“How efficiently can we complete the business task?”
How to reduce LLM token consumption
A practical enterprise strategy is to reduce unnecessary work at each layer.
1. Give the model only relevant information
Use targeted retrieval rather than sending entire document collections.
2. Keep conversation context under control
Retain what the task needs and avoid repeatedly sending irrelevant history.
3. Use knowledge graphs for complex relationships
Let the knowledge layer identify the relevant entities and relationships before retrieving supporting information.
4. Use smaller models for narrow workloads
Route classification, extraction and other repetitive tasks to Custom SLMs.
5. Keep business rules outside the model
If a decision can be made deterministically, use application logic or a rules system rather than consuming model inference.
6. Keep outputs focused
Do not generate long explanations when the next step only requires a structured result.
7. Avoid unnecessary agent steps
Minimise repeated searches, redundant model calls and unnecessary tool use.
8. Reuse repeated information
Use appropriate caching where the same context is processed repeatedly.
9. Route complex requests to the models that need to handle them
A large LLM should be a deliberate choice, not the default for every request.
10. Measure the complete workflow
Track tokens, latency, accuracy, retries, escalation and cost per successful task together.
Token efficiency is not about making AI smaller at any cost
There is an important distinction between efficiency and simply cutting usage.
Reducing context too aggressively can make an answer less accurate.
A smaller model can create more errors if the task is genuinely complex.
A shorter response can leave the user without the information they need.
A retrieval system that finds too little evidence can make the response incomplete.
The objective is therefore not:
use as few tokens as possible.
It is:
Use only the tokens and computation the task actually needs.
That is a much more useful principle for enterprise AI.
What a token-efficient enterprise AI architecture looks like
A practical architecture can combine several layers:
User request
↓
Understand the task
↓
Identify relevant enterprise context
↓
Retrieve only what is needed
↓
Route to the right model
↓
Apply business rules and enterprise data
↓
Generate the required response or action
This means the model is not responsible for everything.
Knowledge handles knowledge.
APIs handle live business data.
Rules handle deterministic decisions.
Smaller models handle specialised tasks.
Larger models handle genuinely complex reasoning.
This is the kind of architecture described across our enterprise AI platform, Custom SLMs and knowledge-grounded AI approach.
Final thoughts
Token consumption is easy to overlook because users do not see it.
They see a question and an answer.
Behind that simple interaction, the system may be processing:
conversation history
documents
knowledge
tool results
instructions
model outputs
and several additional AI steps.
At small volumes, that may not matter much.
At enterprise scale, it matters a lot.
The most effective way to reduce AI costs is not to obsess over the price of every individual token.
It is to build an architecture that needs fewer unnecessary tokens in the first place.
That means:
retrieve less irrelevant information
use knowledge more intelligently
keep context focused
route simple tasks to smaller models
reuse repeated information
avoid unnecessary AI calls
keep deterministic work outside the model
and reserve large-model reasoning for tasks that genuinely need it.
The result is not simply lower token consumption.
It can mean lower latency, lower infrastructure cost, higher throughput and a more efficient enterprise AI system overall.
Frequently Asked Questions
What are tokens in an LLM?
Tokens are pieces of text that a language model processes. For enterprise AI, they can come from user messages, instructions, conversation history, retrieved information, tool results and model responses.
Why does token usage increase AI costs?
In many usage-based AI services, token consumption directly affects the amount billed. Even when models are self-hosted, more tokens generally mean more computation and infrastructure usage.
Why is my LLM using so many tokens?
Common reasons include long conversation history, large prompts, too much retrieved information, repeated context, multiple model calls and unnecessarily long responses.
Does a longer prompt cost more?
A longer prompt generally contains more information for the model to process, which can increase token usage and potentially affect both cost and latency.
How can I reduce LLM token usage?
Start by reducing unnecessary context. Use targeted retrieval, knowledge graphs, shorter prompts, controlled conversation history, smaller specialised models, structured outputs, caching and model routing where appropriate.
Does RAG reduce token consumption?
It can. A well-designed RAG system retrieves only the information relevant to a question instead of sending an entire knowledge base to the model.
Can a knowledge graph reduce AI costs?
It can help reduce unnecessary context by identifying the relevant entities and relationships before document retrieval and generation.
Do smaller models use fewer tokens?
Not necessarily. A smaller model may process the same number of tokens, but it can require less compute and infrastructure to process them. This can reduce the overall cost of the AI workload.
Should enterprises try to minimise tokens as much as possible?
No. The goal is not minimum token usage at any cost. The goal is minimum unnecessary token usage while maintaining the accuracy and context required for the task.
What is the best way to measure AI cost?
Measure cost per successful business task alongside token usage, latency, accuracy, retries, escalation and infrastructure requirements.
Learn More
Explore our enterprise AI platform, Custom Small Language Models, Knowledge Graph and RAG architecture, AI model routing, AI latency architecture, enterprise voice agents, and AI benchmarks.

Bio: Navvya works at the intersection of product strategy and applied AI research at Shunya Labs. With a background in human behaviour and communication, she writes about the people, markets, and technology behind voice AI, with a particular focus on how speech interfaces are reshaping access across emerging markets.